The $25.6 Million Video Call That DISCERN-AI Was Built to Stop
In early 2024, a finance employee at the engineering firm Arup joined a video call with his chief financial officer and colleagues he recognised.
The faces were right. The voices were right.
He wired $25.6 million in fifteen transfers.
Every person on that call except him was synthetic.
That is not a hypothetical.
That is what happens when the only way to check identity is the thing that can be forged.
That call is why I built DISCERN-AI.
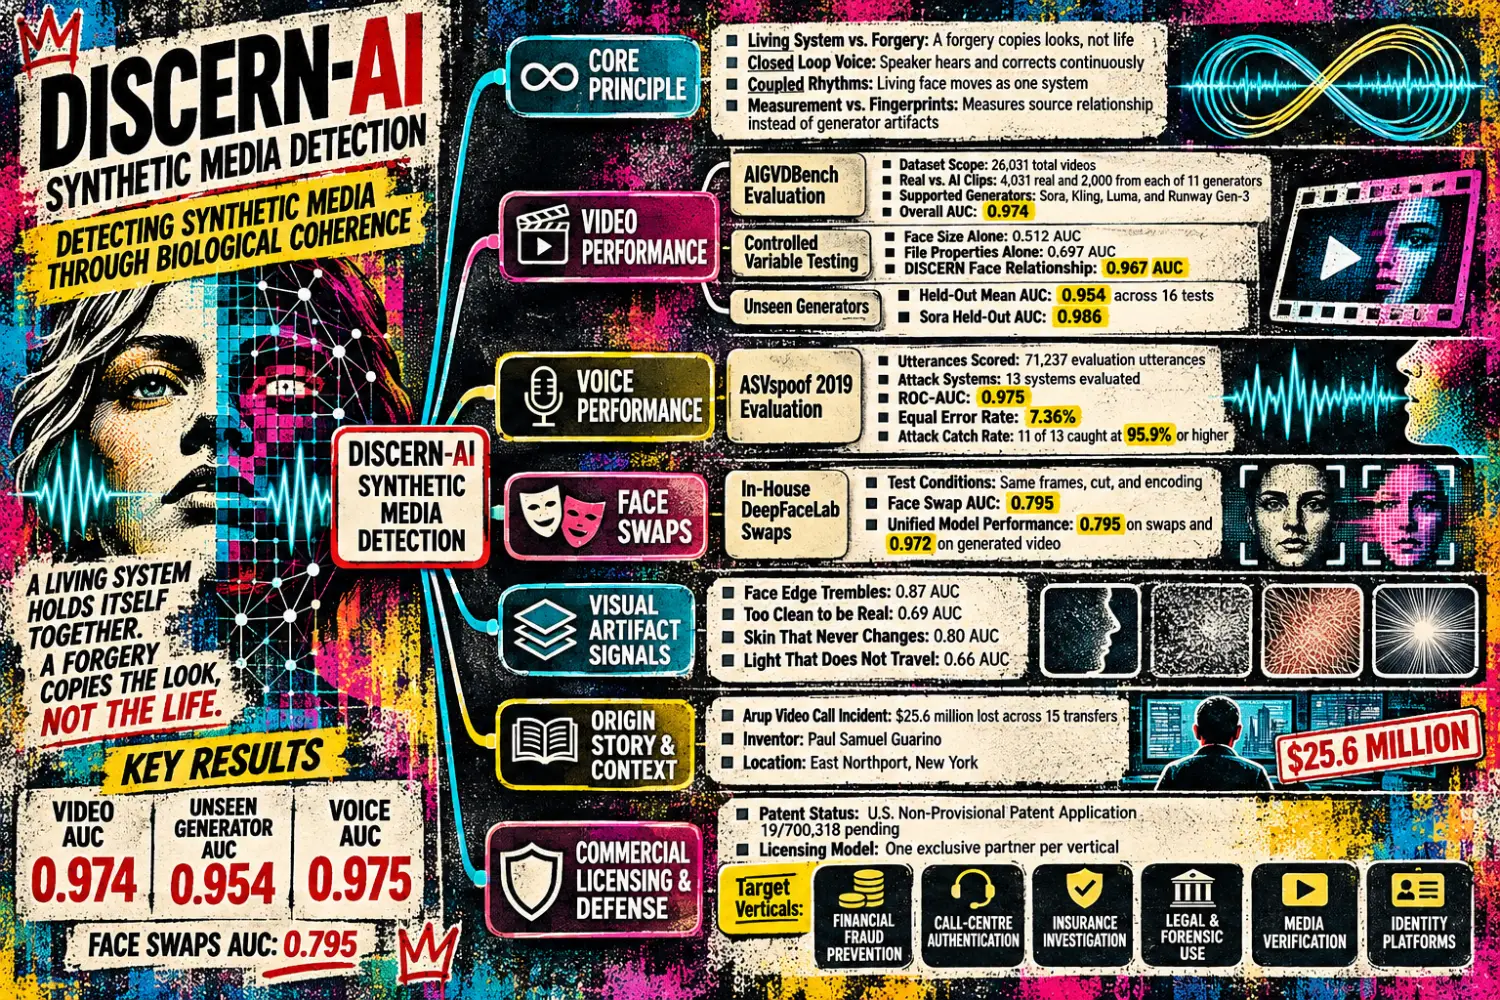
THE IDEA
Most detectors hunt for the forgery.
They learn a generator’s fingerprints, and the fingerprints change with every release. It’s a treadmill, and the forgers control the speed.
DISCERN-AI hunts for the life.
A living voice is a closed loop: you hear yourself as you speak and correct continuously, below anything you’d ever notice.
A living face is held together by coupled rhythms that move as one system, because there is an actual body behind it.
A forgery can copy how you look. It cannot copy how a living body holds itself together.
It can render a picture of that relationship.
It cannot run one.
This is the difference between matching a generator’s artifacts and measuring whether a living system is present.
One breaks every time a new model ships. The other does not.
PROOF, NOT PROMISES
I didn’t design these tests.
That’s the point.
Anyone can check them. The full results document is here.
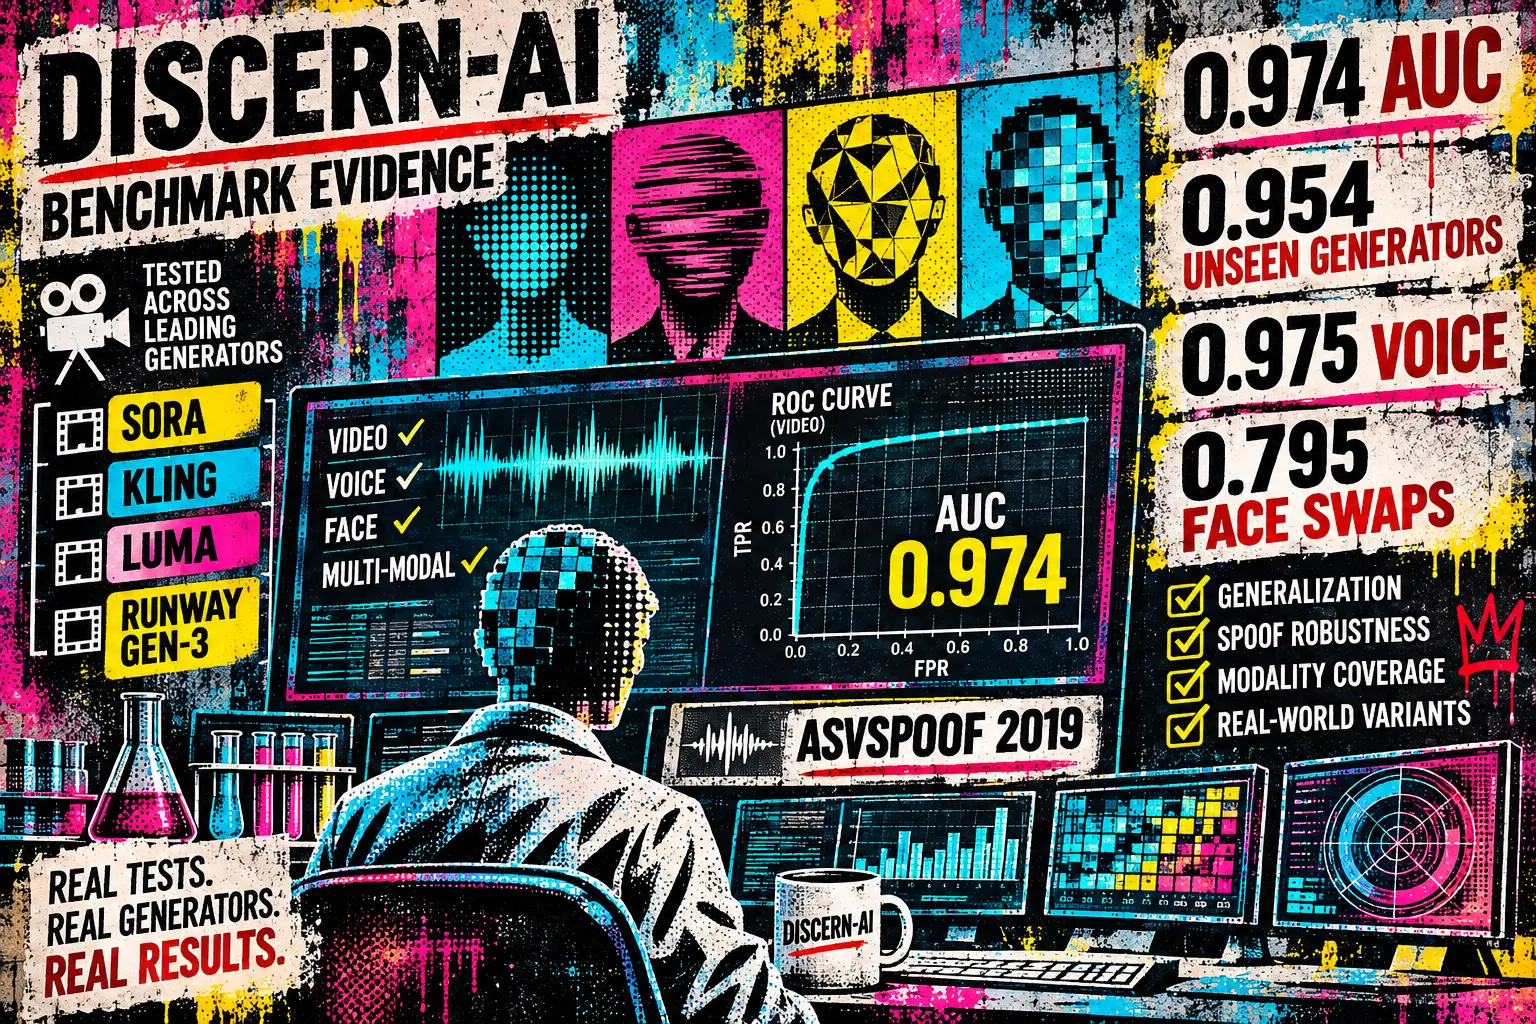
VIDEO
AIGVDBench — L. Ma et al., CVPR 2026
26,031 videos:
- 4,031 real videos
- 2,000 videos from each of 11 state-of-the-art generators
- Generators include Sora, Kling, Luma and Runway Gen-3
Scored: every clip in which one face is held for four seconds — 1,905 clips (1,312 real, 593 AI).
AUC: 0.974
Real and AI clips were matched for:
- Frame rate
- Length
- Resolution
- Encoding
Then came the harder question:
Is it reading the file, or the face?
Every clip was re-encoded identically, and the faces were matched in size.
Face size alone: 0.512. Pure chance.
File properties alone: 0.697.
DISCERN-AI face relationship: 0.967.
The signal is in the face. DISCERN-AI reads it.
But 0.954 is the number that matters most.
That’s the mean across 16 held-out tests: each generator was removed from training, then scored by a model that had never seen a single clip from it.
Sora alone: 0.986.
Read that again.
It catches forgeries from tools it has never met.
Fingerprint detectors break with every new release.
DISCERN-AI was built not to care.
For scale, the strongest detector in the benchmark paper’s own evaluation, Effort, averages 0.941 AUC across these same 11 generators.
That is a different protocol:
Effort was trained on one open-source generator. DISCERN-AI was trained on the other ten generators in the set.
DISCERN-AI: 0.974 overall. 0.954 on generators it never saw.
VOICE
The full ASVspoof 2019 evaluation:
71,237 utterances. 13 attack systems. Every one scored. No sampling.
ROC-AUC: 0.975
Equal error rate: 7.36%
Eleven of thirteen attack systems caught at 95.9% or higher.
For context, the best speech-specialized deep networks reach roughly 1% EER on this set.
DISCERN-AI’s 7.36% comes from a compact set of measured features, not a large neural network trained on speech.
FACE SWAPS
Face swaps put one person’s face onto another person’s real video.
I built them in-house, each paired against its own original:
Same frames. Same cut. Same encoding.
Differing only in the face.
Face swaps, each tested against its own original:
AUC: 0.795
A strict test: everything except the face is genuine footage.
One DISCERN-AI model handles both kinds of forgery:
0.795 on face swaps. 0.972 on generated video.
THE QUESTION A FORGERY CAN’T ANSWER
Deepfakes will keep getting more perfect.
Chasing perfection is a losing race.
DISCERN-AI asks the one question no rendering can satisfy:
Is anything living behind this?
That question has an answer.
And it’s measurable.
This is not a large research team with institutional compute.
This is one inventor, working from home, with a coherence framework that started as a frequency and a topology.
The results above are what that produced.
OWN THE DEFENSE
DISCERN-AI is protected by U.S. Non-Provisional Patent Application 19/700,318, pending, with priority to 13 June 2025.
Licensing is by field of use:
One exclusive partner per vertical. Rights everywhere else retained.
- Financial fraud
- Call-centre authentication
- Insurance investigation
- Legal and forensic use
- Media verification
- Identity platforms
One partner per vertical. When a vertical is taken, it’s taken.
If synthetic media is a threat to your business, you can own the defense your competitors can’t copy.
Because it isn’t a filter. It’s a measurement.
Paul Samuel Guarino
Inventor, DISCERN-AI
East Northport, New York
41.176hz@gmail.com